Mark Whitfield is a highly experienced, SC-cleared Senior Project Manager and IT professional with over 31 years of experience in both public and private sectors, specializing in software development, cloud migration, and IT systems delivery.
He is currently associated with Capgemini (since 2016) and runs a project management resource website, PROject Templates.
Joined Capgemini in 2016 having worked at ascending points in software development lifecycle projects for over 31 years
Key Qualifications & Experience:
Roles: Senior Project Manager, Engagement Project Manager, Delivery Manager, and former programmer.
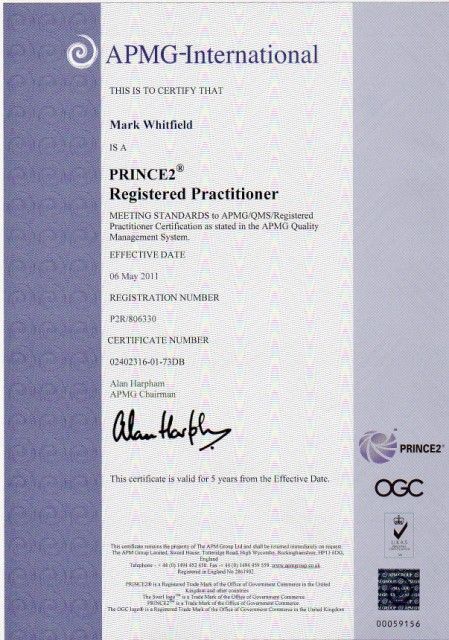
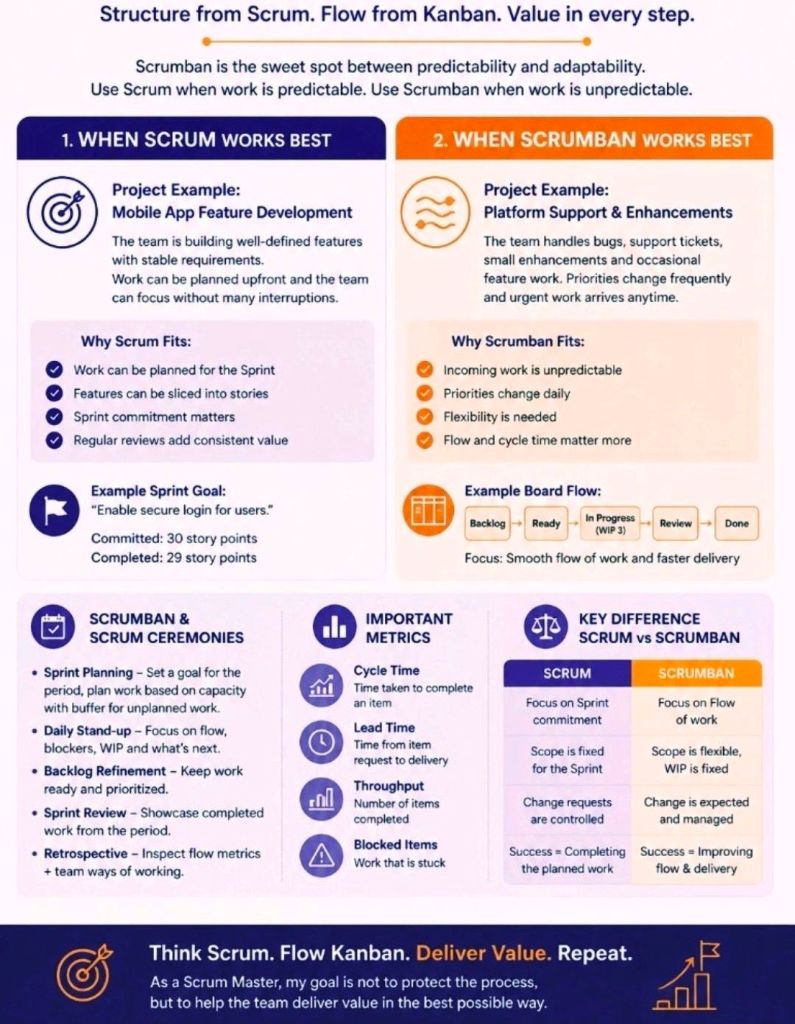
Methodologies: PRINCE2 Practitioner, skilled in both Waterfall and Agile (SCRUM) approaches.
Sector Experience: Extensive experience in finance and banking, including ATM software swap-outs, cloud migration (Azure, AWS, Power Platform), and POS monitoring systems.
Background: Graduated in Computing in 1990; worked as a developer (COBOL, SQL, Tandem / HPE NonStop) before transitioning to project management.
PRINCE2 Practitioner, skilled in both Waterfall and Agile (SCRUM) approaches
Professional Highlights:
Delivered major projects for clients such as Barclays, Bank of England, HSBC, Royal Mail Group, UK & Welsh Government, Heathrow, and Jaguar Land Rover.
Led complex IT infrastructure projects and business transformations.
Maintains mark-whitfield.com, offering over 200 project management templates, trackers (RAID, budget, benefit, cost etc.), and many plans for Agile / Waterfall projects including 30+ Plan On a Page (POaP) and MS Project MPP examples (click on Blog above for a summary).
Provides specialized templates for PRINCE2 7th edition and MS Project (MPP).
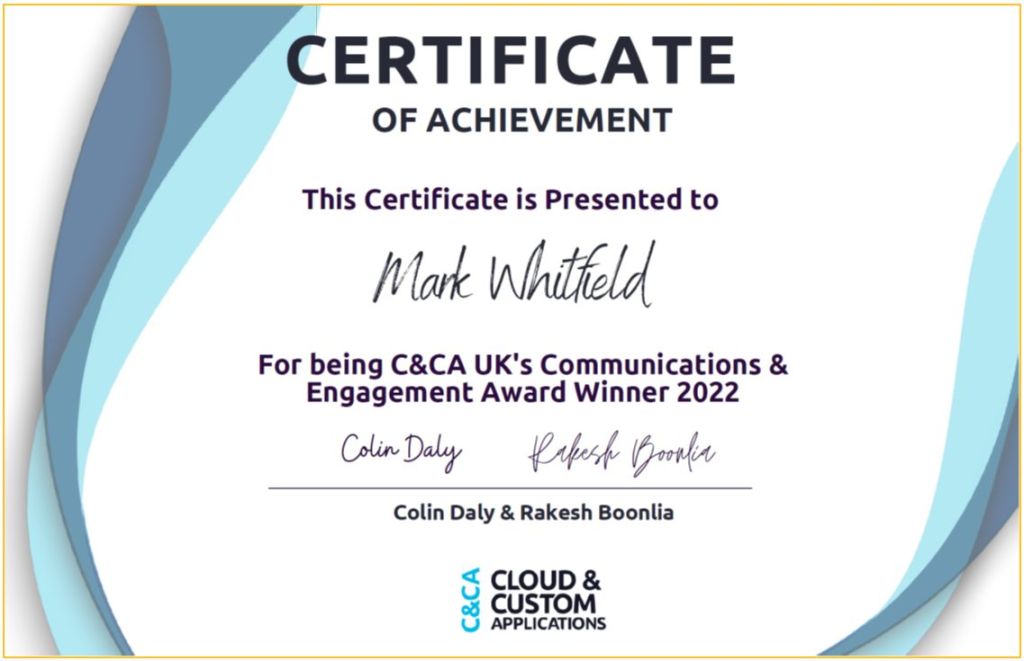
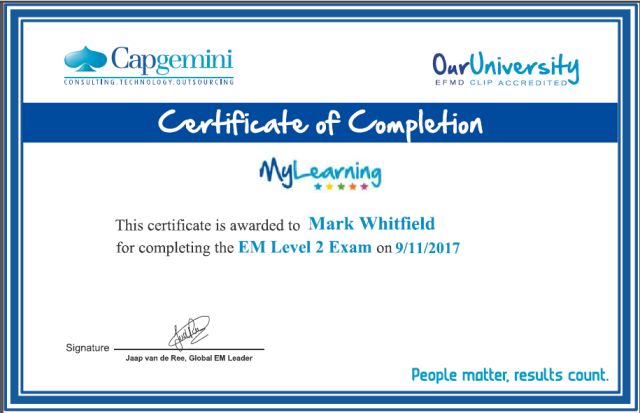
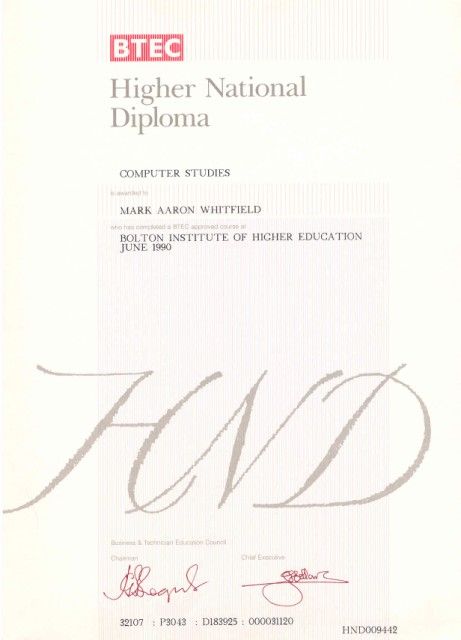
December 2022 – C&CA UK’s Communications & Engagement Award Winner – Cloud & Custom Applications – Capgemini UKNovember 2017 – Advanced Engagement Management Course – Level 2 ExamJune 1990 – Higher National Diploma in Computer Studies, Distinction
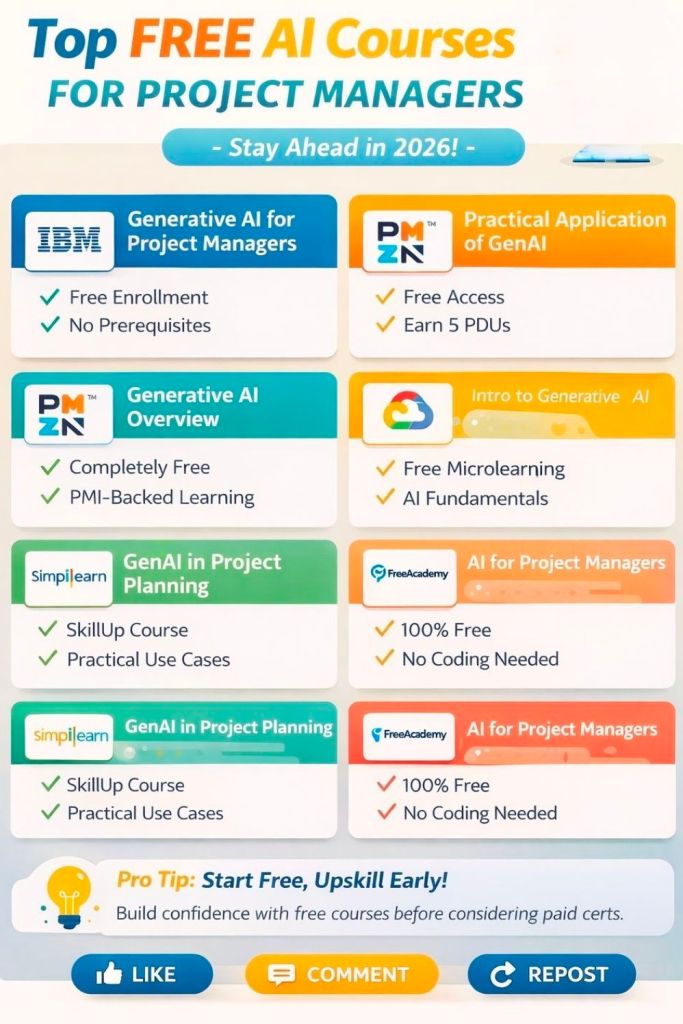
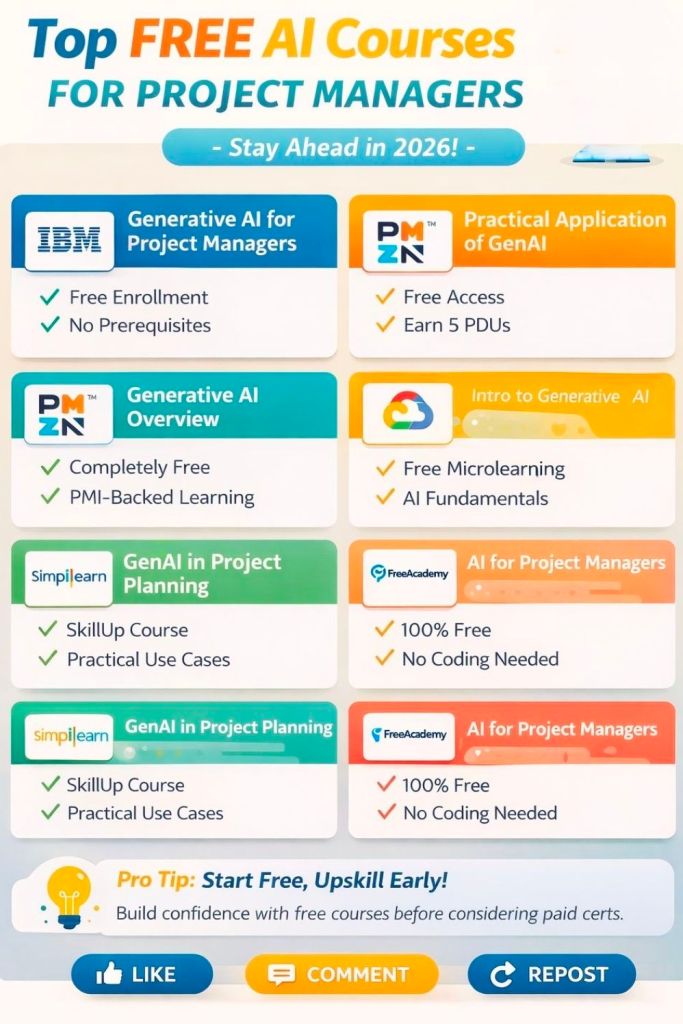
As of 2026, AI is transforming project management by automating scheduling, risk management, and reporting. The best AI courses for project managers (PMs) focus on practical application, generative AI, and AI governance.
Top AI Courses and Certifications for Project Managers
PMI Certified Professional in Managing AI (PMI-CPMAI) (PMI)
Summary: The premier certification for managing AI projects from start to finish, including data prep and model deployment.
Best For: Advanced specialists managing AI projects.
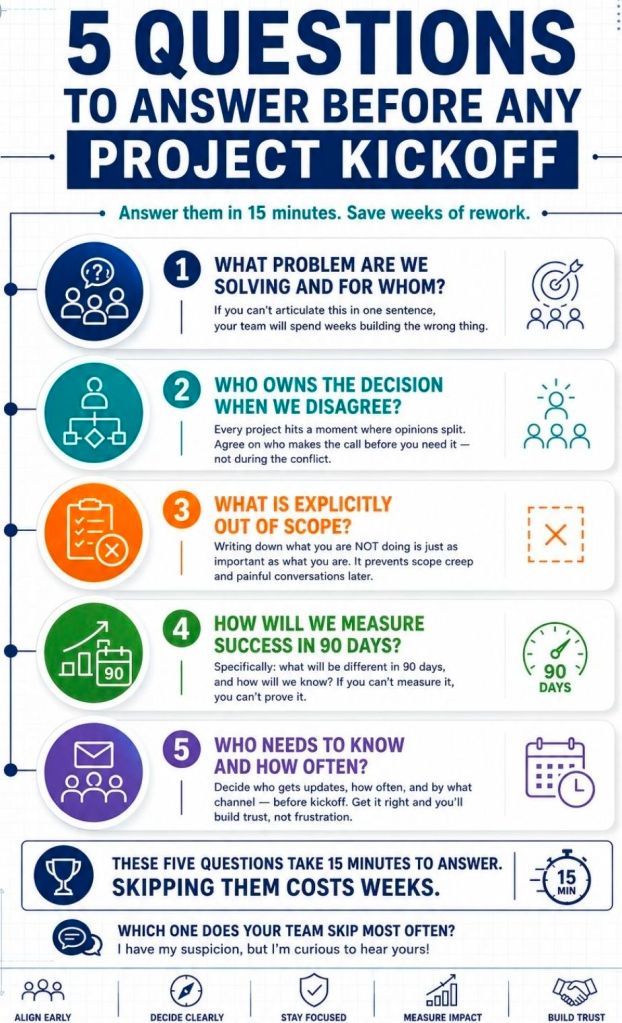
Before launching any project, answering key questions during the initiation phase ensures alignment, prevents scope creep, and sets the foundation for success. These questions help define the “why,” “what,” and “how” of the project, often formalized in a project charter or statement of work (SOW).
Overview: The 5 Ws of Pre-Kickoff
The most effective pre-kickoff approach centers on the 5 Ws + H:
Why: What is the business purpose, problem to solve, or opportunity?
What: What are the high-level objectives, scope, and deliverables?
Who: Who are the stakeholders, sponsors, and team members?
When: What are the milestones, hard deadlines, and time constraints?
Where: Where will work take place (e.g., remote, onsite, systems used)?
How: How will success be measured and how will communication work?
Detailed Description of Essential Pre-Kickoff Questions
1. Context & Rationale (“Why”)
What is the core problem or opportunity? Define the “pain point” triggering this project.
How does this align with company strategy? Understand why this project matters now compared to other priorities.
What happens if we fail or do nothing? This identifies the true urgency.
2. Objectives & Success Criteria (“What”)
What are the measurable goals? Define success (e.g., specific KPIs, revenue increase, time reduction) rather than just stating “improved efficiency”.
What is explicitly in-scope? List the key deliverables.
What is out of scope? Crucial for preventing scope creep—list items that won’t be delivered.
What is the “Minimum Viable Product” (MVP)? What is the absolute bare minimum needed to launch?
3. Stakeholders & Roles (“Who”)
Who is the Project Sponsor? Who is championing the project and ultimately accountable?
Who has final sign-off authority? Identify the key decision-makers to avoid bottlenecks.
Who is the target audience/end-user? Who is this being built for?
Do we have the right skills on the team? Assess the need for external resources or specialized training.
4. Constraints & Logistics (“When” & “Where”)
Is the deadline fixed or flexible? Are there immovable external dates (e.g., conferences, legal compliance)?
What is the rough budget? Have all funds been secured?
What are the key milestones? Identify early dependencies.
5. Risks & Dependencies
What are the major threats? Identify risks to the schedule, budget, or quality early.
What dependencies exist? What outside factors (e.g., vendor delivery, legal approval) must happen first?
6. Operating Model (“How”)
How will the team communicate? Define tools (e.g., Slack, email) and meeting cadence (e.g., weekly, daily standups).
How will we track progress? Where will documentation and tasks be stored (e.g., Jira, Asana)?
Summary Checklist for Pre-Kickoff Success
Business Case Approved: Does a charter exist?
Goals Aligned: Do stakeholders agree on what success looks like?
Constraints Known: Deadline and budget are understood.
Risks Documented: A preliminary risk list is started.
Dependencies Identified: Known bottlenecks are mapped.
Team Identified: Key players are assigned.
Tip: Before the main kickoff, hold one-on-one “sanity check” conversations with key stakeholders to identify unspoken concerns.
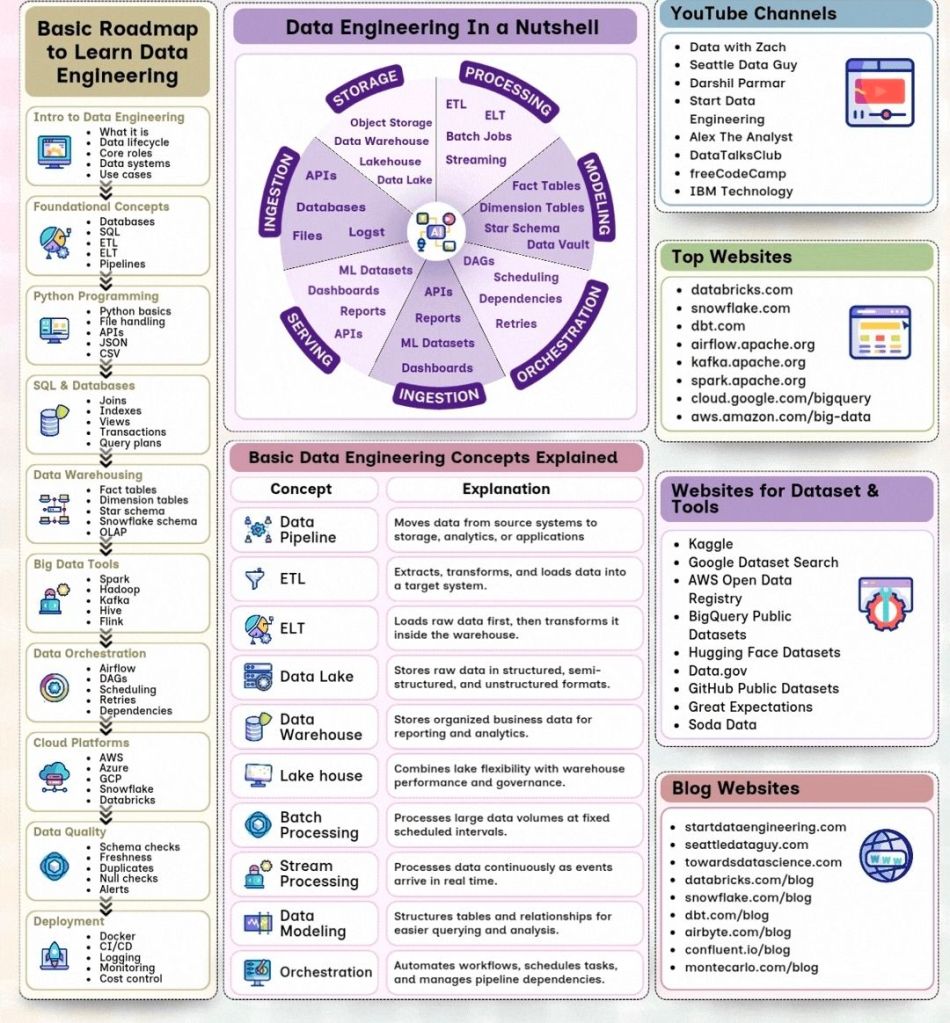
Data Engineering SummaryData Engineering : Step by Step Summary
Extract, Transform, Load (ETL) is a foundational data integration process that consolidates raw data from multiple disparate sources—such as CRM systems, databases, and APIs—into a single, centralized destination, typically a data warehouse or data lake. It is crucial for ensuring that data is clean, consistent, and ready for analytics, BI reporting, and machine learning.
Core ETL Process Steps
Extract: Raw data is pulled from varied sources (structured or unstructured) into an intermediate staging area.
Transform: The staged data is cleaned, formatted, and combined based on business rules to ensure consistency.
Load: The prepared data is moved from the staging area into the final target data warehouse.
Key Benefits
Data Quality & Consistency: Standardizes formats (e.g., date formats, currency) and cleans up errors.
Historical Context: Combines legacy data with new information for long-term analysis.
Automation: Automates recurring data processing tasks, saving time for data engineers.
ETL vs. ELT
ETL (Transform before Loading): Transforms data on a separate processing server before loading, ideal for complex, heavy transformations.
ELT (Load then Transform): Loads raw data directly into the target warehouse (e.g., Snowflake, BigQuery) and transforms it using the warehouse’s power. This is better for large, unstructured datasets.
Detailed Summary
1. Extract
Extraction is the first phase, where raw data is gathered from various heterogeneous sources.
Full Extraction: The entire source is copied; best for small tables.
Incremental Extraction: Only data modified since the last run is extracted.
Update Notification: Source system alerts the ETL tool of a change.
Staging Area: Extracted data is temporarily stored in a “staging area” (or landing zone) to avoid placing heavy loads on production systems during transformation.
2. Transform
This is the most compute-intensive phase, where raw data is converted into a usable format.
Cleansing: Mapping NULL values to 0, removing duplicates, and fixing errors.
Standardization: Converting character sets, date/time formats, or measurement units (e.g., kilograms to pounds).
Data Aggregation: Summarizing data (e.g., total sales per store per day).
Enrichment/Derivation: Creating new calculated values (e.g., calculating profit from revenue and cost).
Encryption/Masking: Anonymizing PII (Personally Identifiable Information) to comply with GDPR/HIPAA regulations.
3. Load
The final phase transfers the cleaned and transformed data into the target destination.
Target Systems: Data warehouses (e.g., Amazon Redshift, Snowflake, Google BigQuery) or Data Lakes.
Loading Methods:
Full Load: Wiping and replacing all data in the target.
Incremental Load: Only loading new/updated data (the “delta”) to the target at regular intervals.
Automation: The process is typically automated to run during off-hours, ensuring the data is ready for morning reports.
Modern Trends and Tools
Cloud-Native ETL: Tools like AWS Glue, Azure Data Factory, and Google Cloud Dataflow allow for serverless, scalable data integration.
Reverse ETL: Moving transformed data from the warehouse back to operational systems (like Salesforce) to activate insights.
Streaming ETL: Processing data in real-time as it arrives, rather than waiting for batch updates, using tools like Apache Kafka.
DataOps: Applying DevOps principles (automation, testing) to data pipelines to ensure reliability and faster deployment.
When to Choose ETL vs. ELT
Choose ETL when: You need to comply with strict data security, perform complex transformations before data hits the warehouse, or have limited computing power in your target database.
Choose ELT when: You are using a cloud warehouse, dealing with massive unstructured data volume, or need high-speed ingestion.